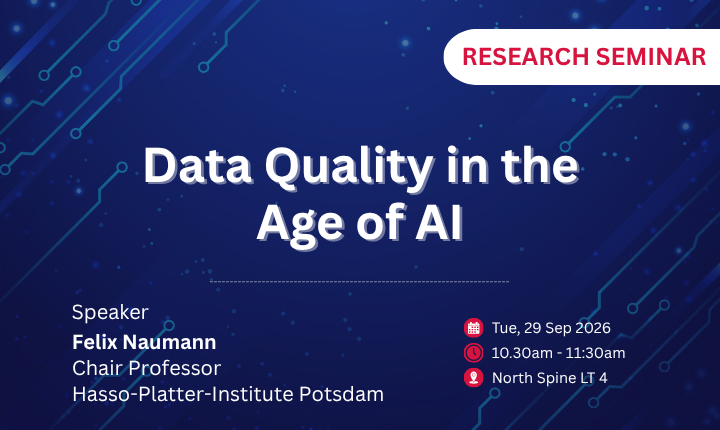
Data Quality in the Age of AI by Felix Naumann
Abstract
Data quality spans multiple dimensions, including statistical accuracy, syntactic correctness, factual validity, and organizational considerations. As data-driven science, machine learning, and AI become increasingly prevalent, the impact of poor data quality has become more significant. Recent regulations, such as the EU AI Act, emphasize the importance of high-quality training data. In the AI era, data quality also encompasses new dimensions such as fairness, diversity, and explainability. This seminar highlights current research in data quality, key challenges, and emerging research opportunities.
About the Speaker
Felix Naumann studied mathematics, economics, and computer sciences at the University of Technology in Berlin and completed his PhD thesis in the area of data quality at Humboldt University of Berlin in 2000. After a Postdoc position at the IBM Almaden Research Center working on data integration topics, he became an assistant professor for information integration, again at the Humboldt-University of Berlin in 2003. Since 2006, he has held the chair for Information Systems at the Hasso Plattner Institute (HPI) at the University of Potsdam in Germany. He has been a visiting researcher at QCRI, AT&T Research, IBM Research, and SAP. His research interests include data profiling, data quality and cleansing, and data integration, recorded in over 200 scientific publications. In addition to numerous PC memberships for international conferences, he has organized several conferences in various roles, including VLDB 2021 as PC co-chair, and he is the Editor-in-Chief of the ACM Journal of Data and Information Quality (JDIQ).