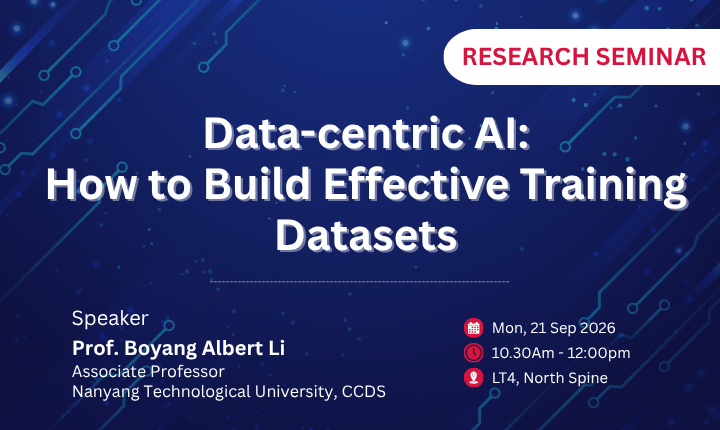
Data-centric AI: How to Build Effective Training Datasets by Professor Boyang Albert Li
Abstract
Scaling training data has been one of the most important performance drivers for AI in the past few years. However, data quality is as important as, if not more important than, data quantity, yet our understanding of the quality of training data and how to identify high-quality data remains limited. While AI engineers perform data cleaning, selection, and training on synthetic data routinely, such activities are usually driven by intuition rather than principled mathematical analysis. In this talk, Professor Li will discuss research from his group on:
- How to select high-quality training data that leads to strong generalization based on both mathematical principles and fast heuristics.
- Training effectively on synthetic multimodal data.
- Estimating the influence of training data on model predictions.
Biography
Dr. Boyang Albert Li is an Associate Professor at the College of Computing & Data Science. Prior to NTU, he worked at Baidu Research USA and Disney Research Pittsburgh. He received his Ph.D. from Georgia Tech. In 2021, he was awarded the National Research Fellowship. From 2021 to 2024, he served as a Nanyang Associate Professor. In 2024, he received a Young Faculty Research Award (Special Mention) from the College of Engineering, NTU. His papers have been allotted oral presentations at ICML 2026, NAACL 2024, and ICCV 2023. His work has been reported by media outlets such as Engadget, TechCrunch, New Scientist, and US National Public Radio.